Agentic Engineering: What It Is, and the Acceptance Problem It Creates
October 1, 2026 · Kealu Team · Engineering
Agentic engineering defined, and why production capacity and acceptance capacity run on different clocks in software whose failure has consequences.
In short
Agentic engineering is the practice of having software agents perform engineering work under human direction: planning, implementing, verifying and documenting changes for which a named person remains accountable. AI is shifting the economic bottleneck in software engineering from production to acceptance. Trust does not scale by itself. Producing the work has become fast. Deciding to accept it moves at the speed of reviewers, evidence and named authority.
What is agentic engineering
That definition is the one this article uses throughout, and the term is already in circulation with a close meaning. Andrej Karpathy, who coined "vibe coding" in early 2025, drew the distinction at Sequoia Ascent in April 2026. In the cleaned-up transcript he published on 30 April: "Vibe coding raises the floor. Agentic engineering is about extrapolating the ceiling." And the part that belongs to acceptance: "Agentic engineering is about preserving the quality bar of professional software." The obligation, in his words, is unchanged: "You are still responsible for your software, just as before."
A note on that source, since this article is about accepting generated work. The same page carries a summary produced by a language model from the video, and the sentences most often quoted from this talk come from that summary rather than from the transcript. The two quotations above are from the transcript section, which Karpathy describes as cleaned up for transcription errors and filler. The distinction cost one reading of the page to establish, and it is the same class of check this article argues for.
The definition above keeps that discipline and adds the part a regulated organization cannot skip: the acceptance is somebody's, by name, and it has to be evidenced.
Three parts of the definition carry weight.
The actor is an agent, and an agent is more than a model call. An agent is a stateful program that calls a model in a loop, keeps context across calls, and uses tools to read and change the world. The model itself is stateless. Our working terminology for agent systems sets out that distinction, the alternatives in current use, and the two senses in which the term "agentic AI" is used today.
The unit is engineering work, and a repository change is one part of it. The work also includes the plan, the interface decision, the test, the rationale, the impact on a neighboring system, and the record of what was checked. An agent that produces the change alone has produced part of the work.
Direction and accountability sit with people. Direction is the instruction and the constraints. Accountability is the part that survives the release: a named person who can explain, months later, why this change was suitable for this use.
Nothing in the definition depends on how capable the agent is. A more capable agent produces more work per hour. The question of who accepts that work, and on what basis, stays where it was.
Two capacities, running on different clocks
A working repository is an instrument. The Kealu white paper AI Has Moved the Bottleneck puts the point plainly: organizations "require reliable behavior in a defined context". Reliable for as long as the system stays in service, and for whoever has to operate, change, audit, secure and support it.
The paper states the shift in one line: "AI is shifting the economic bottleneck in software engineering from production to acceptance." It names the two capacities an engineering organization runs on.
Production capacity refers to the ability to generate designs, code, tests, documentation, analyses, and changes.
Acceptance capacity is the ability to determine whether a particular outcome is suitable for a stated use, supported by relevant evidence, and accepted by an accountable authority.
The paper is explicit that "Although related, these capacities are not interchangeable." Production capacity scales with the agent population. Add another agent, give it a task, and output arrives. Acceptance capacity scales with the number of people qualified to judge a class of change, the evidence those people can get without asking for it, and the speed at which an accountable decision can be made and recorded. Those inputs grow slowly. A reviewer who can judge a timing change in a braking system takes years to develop, and an evidence trail that a second engineer can read without reconstructing the work has to be produced while the work happens.
The paper puts the consequence in one sentence: "An organization can increase its production capacity and reduce delivery performance if review queues, integration burdens, evidence gaps, or unresolved decisions grow faster than the output."
A large-scale measurement is consistent with that attenuation. Demirer, Musolff and Yang matched development records to AI-usage telemetry for more than 500,000 GitHub developers and estimated the effect of each generation of coding tool in a matched event study. Commits rose cumulatively by 240% at the autonomous-agent generation. The same effect falls to 80% for the number of projects worked on, and to 30% for actual releases. The authors' reading: "Large task-level AI productivity gains have therefore translated only partially into shipped and used software thus far." The three figures measure different activities rather than the share of generated code that reaches production, and the source is a working paper rather than a peer-reviewed result (NBER Working Paper 35275, issued May 2026, revised September 2026). What it establishes is the shape: the gain is largest where the work is produced and smallest where it ships.
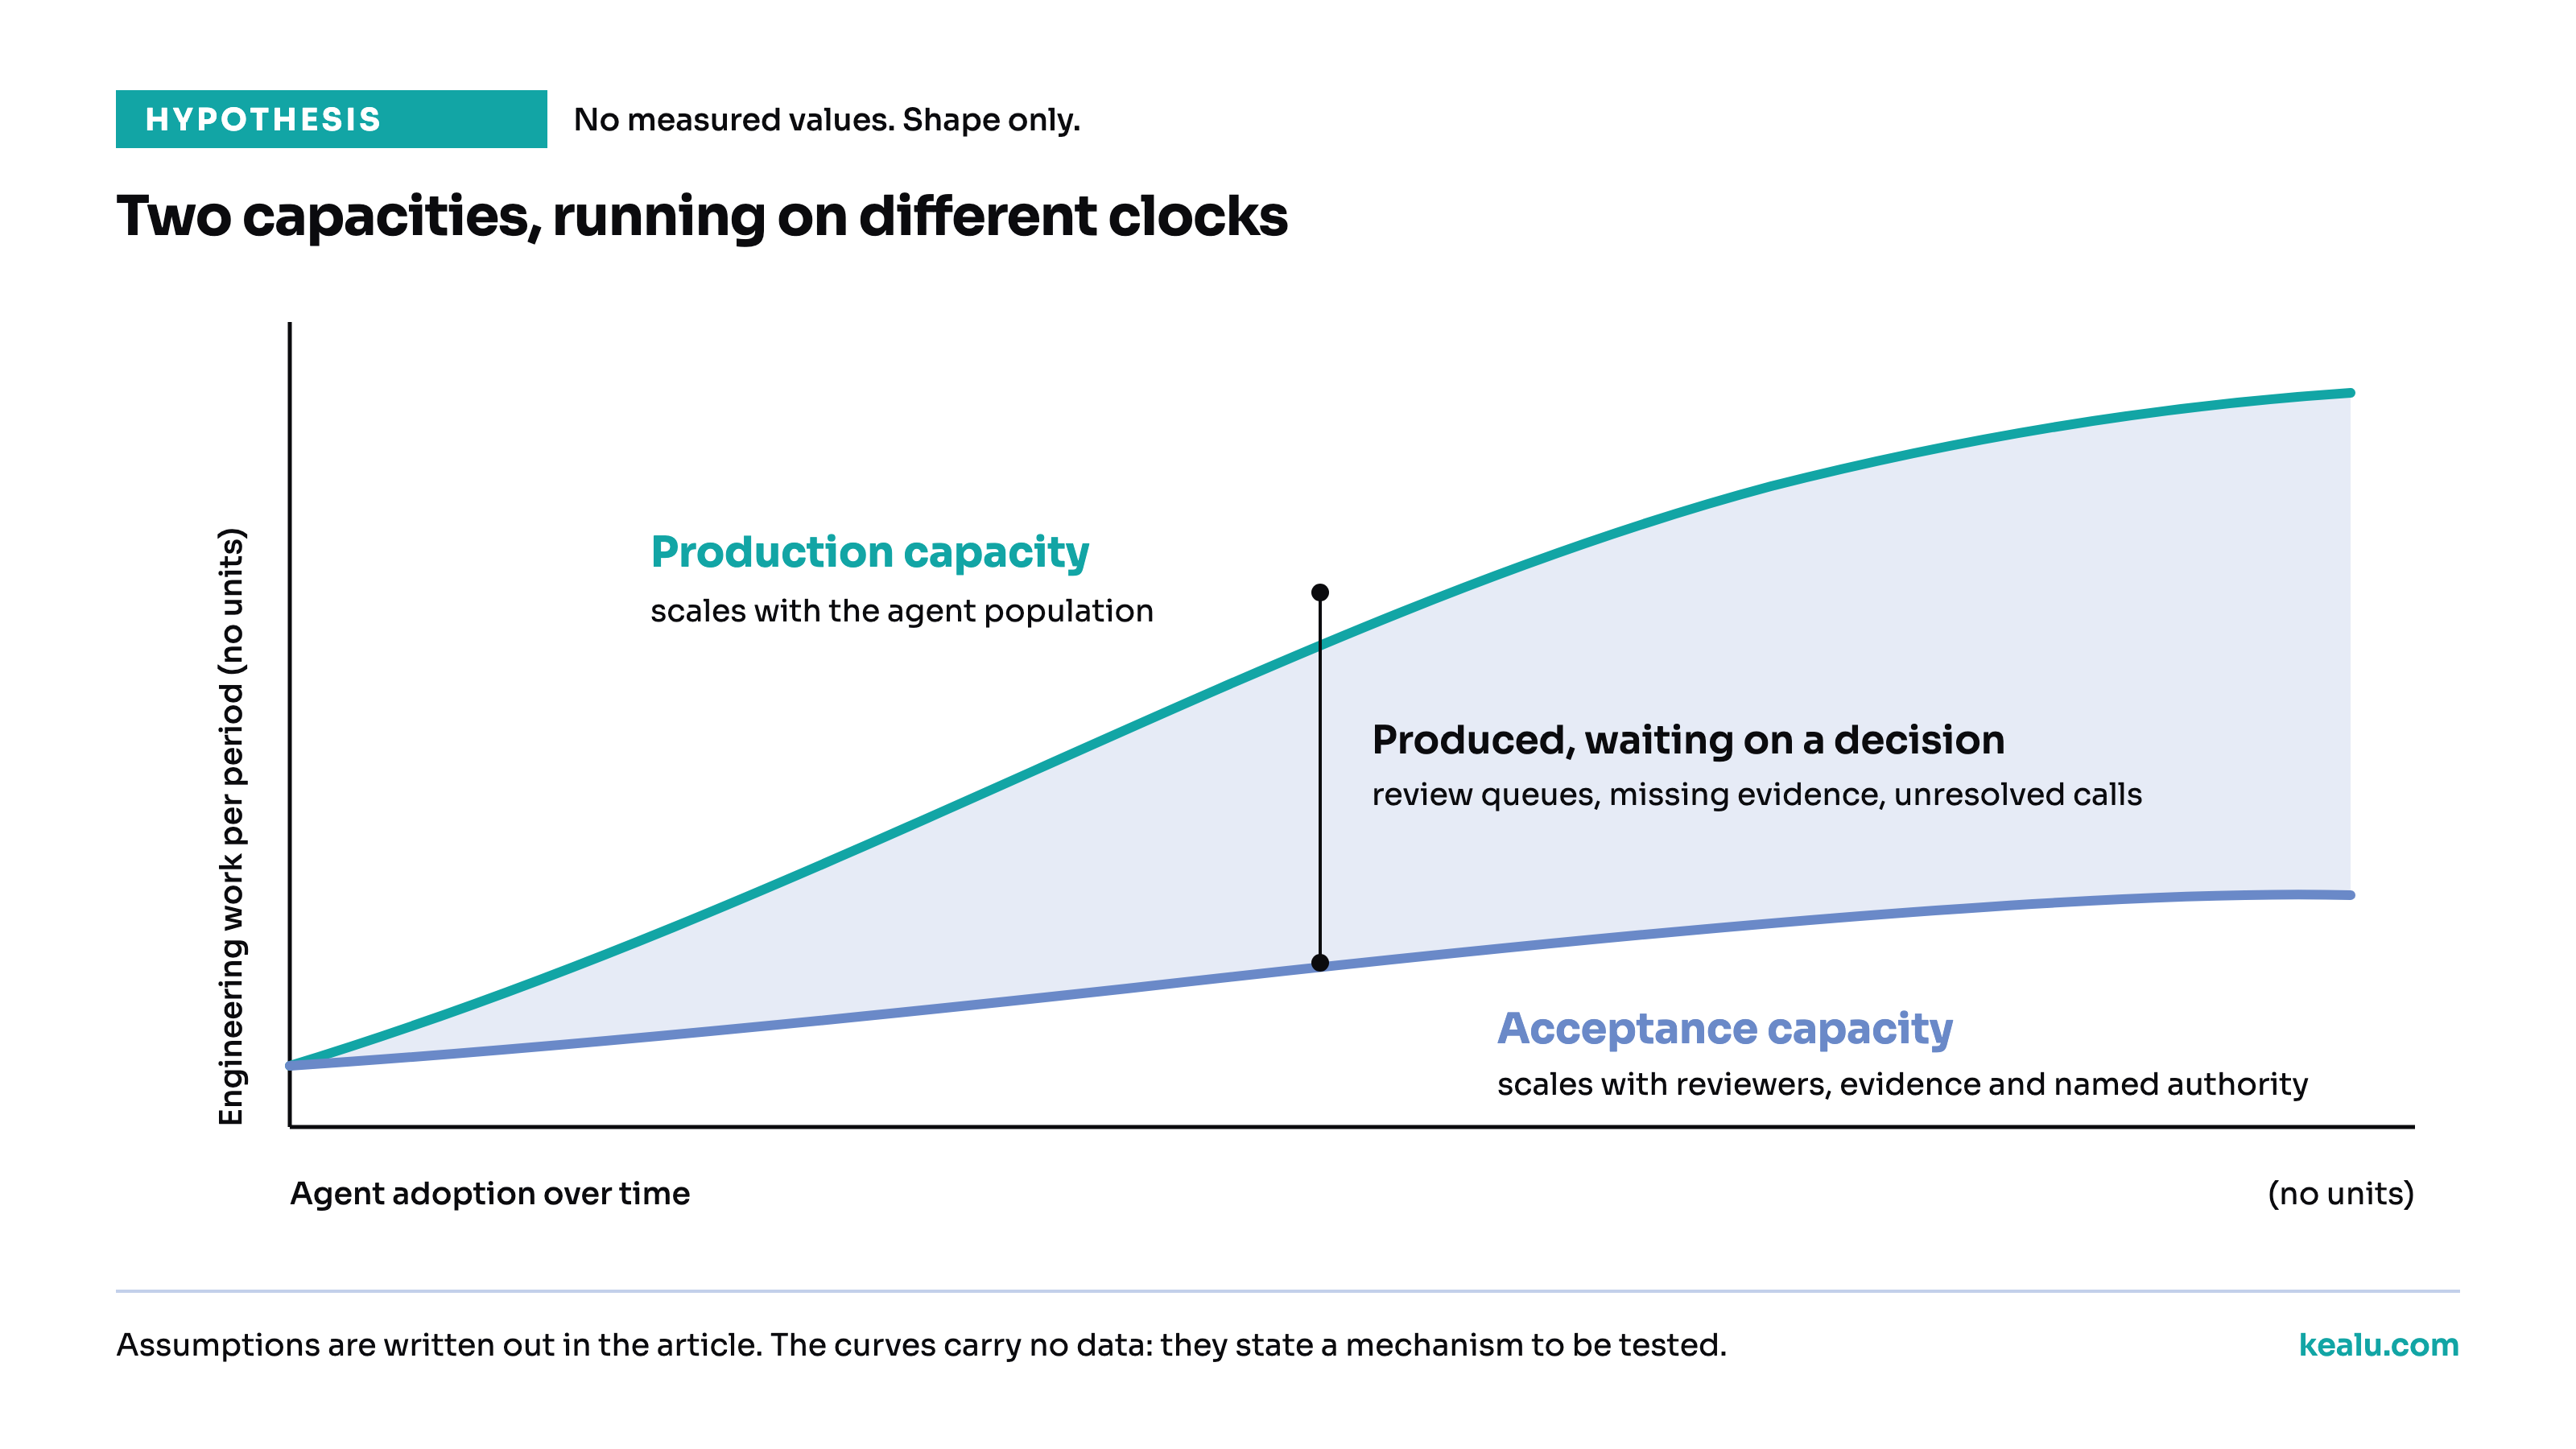
The figure is a hypothesis. Its assumptions, written out:
- Production capacity is treated as roughly proportional to the number of agents a team can direct, with no organizational ceiling inside the period shown.
- Acceptance capacity is treated as growing with qualified reviewers, reusable evidence and verification separated from the producer, all of which move slowly.
- The gap is treated as work in progress: produced, plausible, and waiting on a review queue, a missing piece of evidence, or an unresolved decision.
- The time axis has no units and the curves have no measured values. We have no dataset behind the shape, and the point at which the two lines separate differs for every organization.
- The shape assumes the work is consequential enough to require a decision. Where a change can be shipped and reverted cheaply, acceptance is fast and the gap stays closed.
A curve with no numbers makes a claim about mechanism, which is the part we would like the field to test. Anyone with measurements that contradict the shape has something we want to read.
The maturity illusion
The gap has a way of staying invisible while it opens. The white paper calls this the maturity illusion.
Agentic tools can produce visible functionality quickly; therefore, projects appear to advance sharply. However, system maturity depends on integration, non-functional behavior, evidence, operational constraints, and convergence across disciplines. If these obligations are deferred, the gap is discovered later when architectural flexibility is lower and change is more expensive.
Every status report reads well while this happens. Features demo. Tests pass. The deferred obligations are the ones nobody demos: whether the timing assumptions still hold at system level, and whether an auditor two years from now can follow what was decided and why.
Where acceptance goes wrong
Obvious failures are cheap to reject. The white paper locates the expensive output elsewhere: "Difficult output is coherent, plausible, and almost correct."
The 2025 Stack Overflow Developer Survey used 49,009 responses from 177 countries. Asked which problems they had encountered when using AI tools, 31,476 developers answered, and the frustration at the top of the list, at 66%, was "AI solutions that are almost right, but not quite". Second, at 45.2%, came "Debugging AI-generated code is more time-consuming".
The same survey asked how far developers trust the accuracy of AI output. Its summary of the answers:
More developers actively distrust the accuracy of AI tools (46%) than trust it (33%), and only a fraction (3%) report "highly trusting" the output. Experienced developers are the most cautious, with the lowest "highly trust" rate (2.6%) and the highest "highly distrust" rate (20%), indicating a widespread need for human verification for those in roles with accountability.
The white paper lists the shapes this takes in engineering work.
It may satisfy the prompt while violating an unstated rule. It may generate tests that confirm the assumptions embedded in its implementation. It may use a valid library in an unsupported manner. It may handle the normal case while missing the timing, concurrency, rollback, or degraded-mode requirements.
The output is good enough that the constraint has moved downstream of it. Any capable contributor working without the unstated context produces the same class of defect. Agents change the volume and the speed at which it arrives.
The paper itemizes the bill: the cost of converting that into accepted engineering work "is paid through senior review, architectural reconstruction, integration debugging, test expansion, compliance mapping, and operational caution." None of it appears at the moment the agent finishes.
The measurement problem
It is tempting to settle all of this with a productivity number. One randomized trial, and its sequel, show how hard that is.
In July 2025, METR published a randomized controlled trial. Sixteen experienced open-source developers worked on 246 real issues from repositories they had contributed to for years, each issue randomly assigned to allow or disallow AI. The result: developers took 19% longer when AI was allowed. A second finding in the same study speaks more directly to acceptance.
This gap between perception and reality is striking: developers expected AI to speed them up by 24%, and even after experiencing the slowdown, they still believed AI had sped them up by 20%.
Self-assessment of how much faster the work went proved unreliable even for experienced engineers in familiar code.
METR now labels that result out of date. In February 2026 the team published its reasoning for redesigning the experiment. The second study ran from August 2025 with 10 developers from the original group plus 47 newly recruited ones, at $50 an hour instead of $150. The raw results point the other way: an estimated 18% speedup among the returning developers, 4% among the new ones. Both confidence intervals cross zero, running from a 38% speedup to a 9% slowdown for the returning group and from a 15% speedup to a 9% slowdown for the new one. The team is direct about why it distrusts its own numbers.
An increased share of developers say they would not want to do 50% of their work without AI, even though our study pays them $50/hour to work on tasks of their own choosing. Our study is thus systematically missing developers who have the most optimistic expectations about AI's value. [...] When surveyed, 30% to 50% of developers told us that they were choosing not to submit some tasks because they did not want to do them without AI.
Based on conversations with study participants, we believe it is likely that developers are more sped up from AI tools now [...] compared to our estimates from early 2025. However, because of the selection effects in our experiment, our data is only very weak evidence for the size of this increase.
One thing follows for acceptance. A production-speed number, on its own, makes a weak basis for deciding how much agent-produced work an organization should take on, and METR's own account shows how quickly such a number goes stale. The evidence an organization needs sits in its own queue, its own review record and its own defect history.
The five conditions acceptance runs on
A decision about suitability needs material to decide on. The white paper calls for "an independent Assurance Plane that governs how agentic engineering work is performed and evidenced", which "must preserve five conditions: independent verification, validation against authoritative intent, named human authority, transferable evidence, and evidence freshness." That Assurance Plane is the thing Kealu names the Agentic Engineering Assurance Layer. Our reading of each condition:
| Condition | The question it answers | What it produces |
|---|---|---|
| Independent verification | Who checked this, and how far from the producer do they stand? | A check whose result does not depend on the assumptions of the work it is checking |
| Validation against authoritative intent | Was the right problem solved? | A comparison of the result against the authoritative intent and intended use |
| Named human authority | Who accepted this, and on what basis? | A person or authorized role attached to the decision, with the uncertainties they were shown |
| Transferable evidence | Can somebody else reach the same conclusion later? | A record another qualified person can read without reconstructing the work |
| Evidence freshness | Is the evidence still valid today? | A link between each claim and what it depends on, so a change can flag what went stale |
Independence is the condition that is easiest to appear to satisfy. An agent that writes an implementation and then writes the tests for it has verified very little: the tests inherit the misunderstanding. What makes a check worth reading is separation between the thing that produces and the thing that checks, and how much separation a piece of work needs is a risk decision rather than a fixed setting. The white paper gives the range: "Depending on the consequence, independence may require a separate agent, model, method, tool, environment, organization, or human specialist."
The bottom of that range is the part most often mistaken for the whole of it. A different model or a different prompt changes who does the checking without necessarily changing what the checking rests on: the same intent, the same unstated assumptions, the same context assembled the same way. That is separation of execution, not separation of judgment, and it is not by itself a guarantee of independent judgment. At the integrity levels where a failure costs lives, the separation that counts sits at the far end of the range and is organizational: an organization other than the one that produced the work. Between those two ends the answer is a risk decision, proportionate to consequence and to the customer's own policy.
Evidence has a shelf life. A dependency update, a standard revision, a change in a neighboring component, and an assurance claim that held in March is unsupported by September, with nothing in the system saying so.
Consequential Software: where the gap gets expensive
For much software, a change that ships in the morning, is observed by lunch and is reverted in a minute carries its own verification. The acceptance question gets expensive in a specific class of system, which the white paper names.
Consequential Software is software whose failure, degradation, manipulation, unavailability, or untraceable change can materially affect human safety, health, financial integrity, essential services, legal obligations, or the operation of a complex system, and whose acceptance therefore requires lifecycle evidence and an accountable technical authority beyond local functional correctness.
The paper classifies by mechanism: a useful classification "asks how consequences are produced." Five dimensions do most of the work, and a sixth matters for long-lived products.
- Severity. What happens if the software is wrong, unavailable, manipulated or misunderstood. This sets how much evidence and how much authority the decision needs.
- Coupling. How many physical, software, data, supplier and organizational systems depend on the behavior. Where coupling is high, local correctness stops predicting system behavior.
- Reversibility. Whether the change can be rolled back and its effects undone. Slow or partial reversibility moves the burden of proof in front of the action.
- Observability. Whether a failure will be noticed quickly and unambiguously. Silent or delayed failures weaken the correction that fast rollback is assumed to provide.
- Accountability. Whether a named person or institution has to defend the decision to a customer, a regulator, an operator or the public.
- Lifecycle duration. Complex products stay in service for decades, and the evidence has to survive changes of team, tooling and organization.
The paper works the point through three composite scenarios, one of them from financial infrastructure. An agent changes the retry logic of a payment-processing service, adds backoff and idempotency keys, and "runs unit and integration tests, and they pass." Then: "A retry that is safe before authorization may be unsafe after a partially completed settlement step". The operational dashboard can show successful retries while a downstream ledger records duplicate economic events. The risk lives in a relationship outside the visible feedback surface. A qualified human or an independent system has to reconstruct that relationship before anybody accepts the change.
What a team can change without buying anything
Most of the acceptance problem is organizational, and a team can start on it with the tools it already runs.
Record what produced the change. Store the agent, the model identifier and date, the instruction and the tools used alongside the diff, in the same place the diff lives. A hosted model can change behind a stable name, so the record establishes what was used and does not reproduce the run. Provenance is cheapest to capture while the work happens.
Split the producer from the verifier, and record how far apart they are. A different agent with different instructions separates execution, not judgment: it is where the range starts, not yet a form of independence. A deterministic tool, an existing analysis system, a second person, an independent team and a separate organization each add something the previous one lacks, and the companion paper is explicit that "Independence can be technical, organizational, or methodological" rather than one axis. Write down which one checked the work, so the strength of the check travels with its result. Choose the point on the range from the consequence of being wrong, not from what is convenient to automate.
Write the intent before the work starts. One paragraph of authoritative intent, including the constraints that usually go unstated, gives the verifier something to validate against. Without it, review collapses into reading the implementation and guessing at the goal.
Name who accepts, for each class of change. A person or an authorized role, decided in advance, with the uncertainties, conflicts and exceptions routed to them for a recorded decision. A policy threshold and a passing pipeline feed that decision; the decision itself carries a name.
Date the evidence. Every check gets a timestamp and a list of what it depended on. When one of those dependencies moves, the affected work can be listed and re-checked.
Measure the queue. Count the work that has been produced and is waiting on a decision, and how long it waits. That number describes acceptance capacity directly, and it moves early.
All six run on tools a team already has, once the record is treated as part of the work.
Questions we have not settled
We put this category forward to be tested.
Where on the independence range does a given system belong? The ends are not in question: producer-written tests are not independent, and at the highest integrity levels independence is organizational. The middle is open. Which combinations of severity, coupling and reversibility justify which point in between, at what cost, is unsettled, and the standards that govern this work were written when the producer was always a person. Those standards already handle tools whose output cannot be trusted on its own, through tool qualification and tool confidence levels, DO-330 being the aerospace instance. Whether a coding agent is a tool in that sense, and what qualifying one would mean, is unsettled.
Does evidence produced during agentic work satisfy an assessor? Assessors read evidence packs built by humans for human processes. Whether a record generated while an agent worked is accepted as equivalent is an open question in each assessment regime.
What is the right unit of acceptance? We model it as a bounded work package carrying its intent, its checks, its evidence and its decision. A pull request fits poorly: it bounds a set of code changes, and the engineering obligation around them is only implied. Better units may exist.
If you run Consequential Software and have views on any of these, we would like to hear them.
Frequently asked questions
What is agentic engineering? Agentic engineering is the practice of having software agents perform engineering work under human direction: planning, implementing, verifying and documenting changes for which a named person remains accountable. It describes a working arrangement, and it applies whichever tools a team uses.
Is agentic engineering the same as vibe coding? No. Vibe coding, the term Karpathy coined in early 2025, describes building by describing what you want and accepting what comes back. In his words it "raises the floor", while agentic engineering "is about extrapolating the ceiling" and about "preserving the quality bar of professional software". Agentic engineering covers the whole working arrangement: who directs the agents, what evidence the work produces, and who accepts the result.
Who is accountable for code an agent wrote? The same authority that would have been accountable had a contractor or a junior engineer written it: the named person who accepts the change. Agents can originate, analyze, produce, and contribute to verification when they are separated from the work they are checking. How much separation that takes is set by the consequence of being wrong, and at the highest integrity levels it is organizational. A person makes and records the acceptance decision.
Does agentic engineering require new standards? In our view the existing obligations already cover it: what these regimes require of evidence and of who signs holds regardless of what did the typing. The open work is how the evidence gets produced, and how much of it has to be captured while the work happens. This series takes it one standard at a time, starting with requirements traceability and IEC 62304, then functional safety, IV&V, Automotive SPICE and DO-178C.
How is acceptance capacity different from code review? Code review is one input. Acceptance also covers validation against intent, independent verification, the freshness of the evidence, and a recorded decision by somebody with the authority to make it.
Where this goes next
The white paper AI Has Moved the Bottleneck states the case in full, defines Consequential Software and names the five working conditions; its companion specifies the technical obligations. The vocabulary this article uses for agents, sessions and tools is fixed in a working terminology for agent systems. The standards pieces named above follow in this series.
The Agentic Engineering Assurance Layer is the proposed category for the layer that governs how agentic engineering work is performed and evidenced, so that humans can trust and accept the resulting work. The companion white paper develops it as a vendor-neutral category, and the conditions above hold whatever tools a team uses to meet them. Kealu Vector, currently designated Vector Assurance Assist, is our early-access implementation of that category. What this article says about it describes an intended approach, not measured product results. This article is about the problem itself.